
AVAM: a Universal Training-free Adaptive Visual Anchoring Embedded into Multimodal Large Language Model for Multi-image Question Answering
Abstract
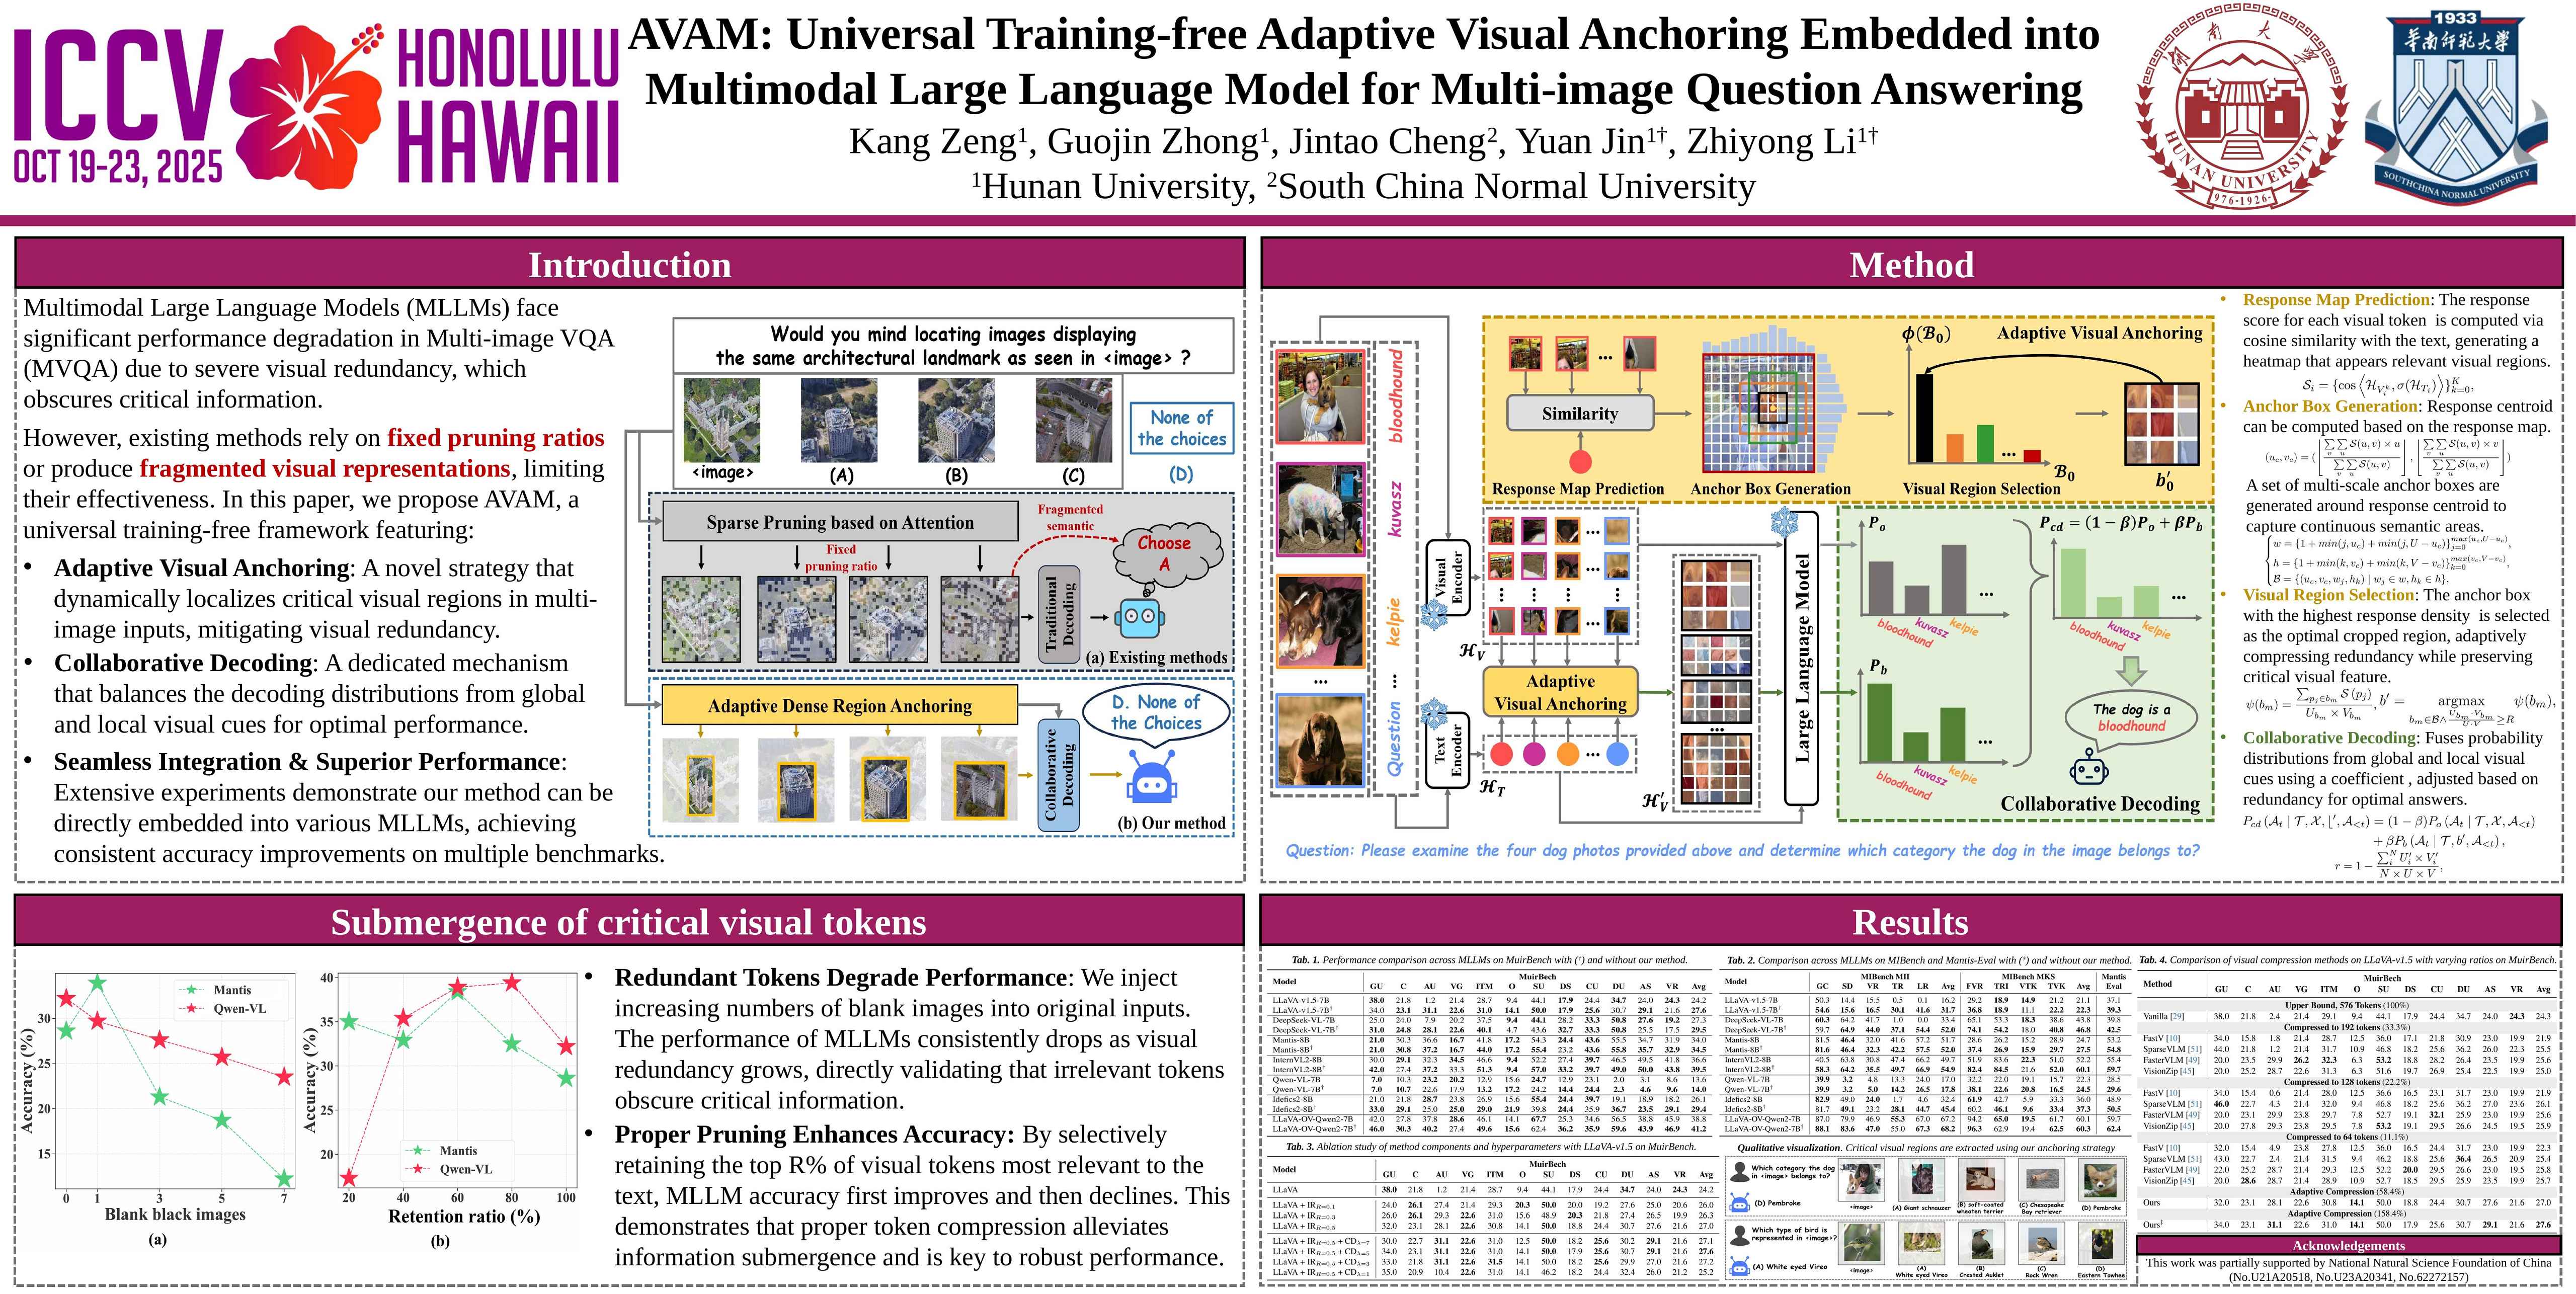
The advancement of Multimodal Large Language Models (MLLMs) has driven significant progress in Visual Question Answering (VQA), evolving from Single-Image VQA to Multi-Image VQA (MVQA). However, the increased number of images in MVQA inevitably introduces substantial visual redundancy that is irrelevant to question answering (QA), negatively impacting both accuracy and efficiency.To address this issue, existing methods often lack flexibility in controlling the number of compressed visual tokens and tend to produce discrete visual fragments, which hinder MLLMs' ability to comprehend images holistically.In this paper, we propose a straightforward yet universal Adaptive Visual Anchoring strategy, which can be seamlessly integrated into existing MLLMs, offering significant accuracy improvements through adaptive compression. Technically, our approach first constructs a response map that captures local relevance within an image concerning a given textual question by measuring cross-modal similarity. Next, a series of anchor boxes are generated around the gravity center of the response map, with the highest-confidence box selected and fed into MLLMs for question answering. To further enhance performance, we introduce a novel collaborative decoding mechanism that balances the answering results derived from both global and compressed images. Since compressed images effectively filter out irrelevant visual regions, they enable MLLMs to establish a more precise alignment between visual and textual content, thereby improving answer accuracy. Extensive experiments validate the effectiveness of our method, demonstrating consistent performance improvements across various MLLMs. The code will be publicly available.